Alternative to Cloudera and Databricks.

Features Icon

Open and cost-effective – Unlike proprietary platforms like Cloudera or Databricks, Ilum is an open platform that’s free to use. You maintain full control over your data, analytics, and AI workflows with no expensive licensing fees and zero vendor lock-in.

Data Lineage

Tracking your data’s journey doesn’t have to be a headache. With Ilum’s automatic data lineage, you’ll always know who, when, and how changes were made to your tables. Every transformation, whether through Spark jobs or SQL queries, is automatically captured in the data lineage view—no setup required.

Built on the Open Lineage framework, Ilum ensures compatibility with industry-leading tools while giving you the ability to track the full history of your tables.

Simplify data tracking and stay in control with Ilum’s robust data lineage feature.

Data Exploration

Ever wanted to quickly understand what your data looks like before diving into complex analysis? Ilum’s built-in data exploration tools make it effortless to inspect your data’s shape, distribution, and key characteristics—all without the need for complex queries or scripts.

Ilum also features a fast visualization tool, allowing you to create charts like bar graphs or scatter plots on the fly. With just a few clicks, you can transform raw data into clear, visual insights right within the platform.

And the best part? There’s no need to export your data to external tools. Everything you need to explore, visualize, and understand your data is integrated directly into Ilum, so you can focus on what matters most—your analysis.

SQL Editor

Ilum’s SQL Editor simplifies querying and data management. Run queries using Delta, Iceberg, Hudi, or Spark SQL from a familiar interface, and save your queries for future use. You can also explore your databases, tables, and schemas directly with the built-in resource structure view.

The editor integrates with Ilum’s data exploration tools, so you can quickly check distributions or create simple charts without leaving the platform.

Future support for Trino, Flink, and Hive SQL will make it even more versatile, handling multiple engines in one place.

Notebook

Ilum includes Jupyter Notebooks as a fully integrated module, so you can start using them without any external setup. From the notebook interface, you can leverage the full power of your remote cluster through Spark microservices, accessing all available memory, compute, and storage resources.

Create a Spark session and use Sparkmagic syntax to run your code or SQL queries directly on the cluster. This ensures you’re not limited by local resources and can fully utilize the platform’s scale.

To help you get started, Ilum includes several tutorial notebooks covering advanced use cases like the Medallion architecture, geospatial analytics with Apache Sedona, and more—all available within the same interface.

BI Integration

Ilum offers seamless BI Integration with a built-in JDBC interface, allowing you to connect tools like Tableau, PowerBI, or Apache Superset directly to your data lakehouse. This gives you instant access to all your defined data without any additional steps.

Everything runs through Spark, so you can configure and scale it to handle workloads of any size—from generating small reports to powering large, complex dashboards.

Data Catalog

Ilum’s Data Catalog keeps your tables and databases organized in one place, eliminating the hassle of hunting for data across different tools. Currently, Ilum integrates with Hive Metastore, offering a reliable way to manage your metadata.

In the next version, we’re planning to make Unity Catalog the default, while still supporting multiple catalogs like Hive, Unity, and Apache Nessie.

Additionally, we’re working on adding support for standard databases like PostgreSQL and MS SQL, so you can plug them into the same interface, making data management simpler and more centralized.

Spark Microservices

Ilum’s Spark Microservices solve the problem of long initialization times in Spark jobs. Instead of waiting 20–40 seconds for each job to start, Ilum uses long-lived Spark sessions that initialize once and handle subsequent API calls instantly, eliminating delays.

This feature is perfect for advanced workflows like Retrieval-Augmented Generation (RAG). You can create a microservice that fetches context-specific data from web pages or documents, processes it, and exposes the results via an API. Integrate this API into tools like chatbots for real-time, context-aware answers, making RAG workflows scalable and efficient.

Spark Jobs

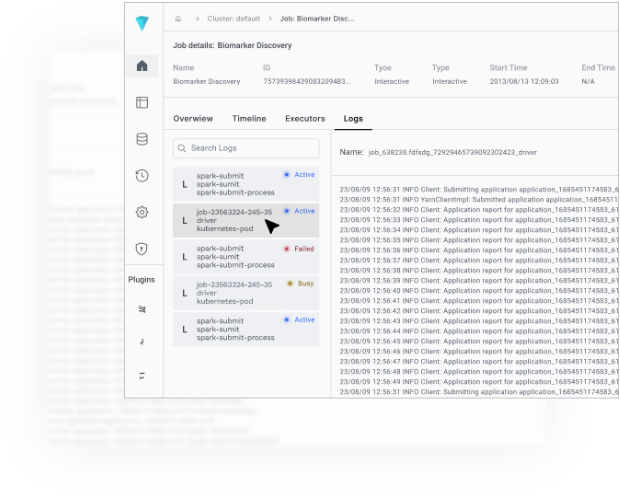
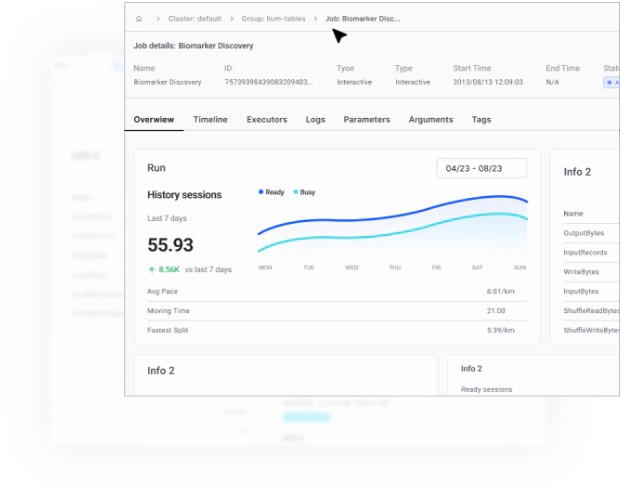
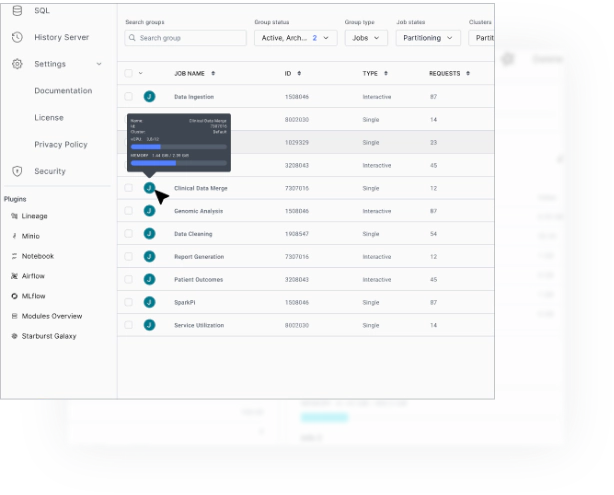
Ilum simplifies running Spark Jobs on Kubernetes, providing all the tools you need in one platform. You can launch jobs through the UI or REST API, schedule them, and tweak configurations to match your workload.

With the Spark History Server set up out of the box, you get full visibility into job performance directly in the UI. For deeper insights, Ilum integrates with Grafana dashboards, allowing you to monitor metrics and optimize your jobs effectively.

Ilum removes the overhead of managing Spark on Kubernetes, eliminating complicated setups or troubleshooting. Whether it’s small queries or processing terabytes of data, Ilum is ready to handle it efficiently.

Modules

Ilum’s Modules are designed to streamline complex data engineering workflows by integrating preconfigured components directly into the platform. These modules are ready to use from the UI, eliminating the need for separate setups or manual integrations.

Current modules include Apache Superset for BI visualizations, Apache Airflow for workflows, and MLflow or Jupyter Notebooks for machine learning. Upcoming additions like dbt, Apache NiFi, and Mage.ai will further enhance the platform's flexibility.

The goal is simple: bring the tools you already know and rely on into a unified ecosystem, so you can focus on engineering solutions without jumping between platforms.

Multi Cluster Support

Ilum’s Multi-Cluster Support allows you to connect and work with multiple clusters, even if they’re different types like Kubernetes, YARN, or local clusters for debugging.

This flexibility lets you manage migrations, run benchmarking tests by executing the same job on different clusters, and compare performance with ease. It’s also ideal for team management, where you can create isolated environments using Kubernetes namespaces to allocate resources without interference.

Additionally, you can configure clusters with different settings or storage solutions, and Ilum will handle the rest by injecting the correct configurations directly into your Spark jobs.

Built for Data Exploration

Your data, secure and accessible

Jupyter Notebooks are integrated directly into Ilum, enabling seamless data exploration and analysis within a secure platform environment.

Your data, secure and accessible

Build Real-time Interaction with Spark Session from UI and API

Leverage seamless integration between Spark Streaming and Object Storage to enable real-time data processing. Achieve millisecond latency by connecting your Spark sessions directly to your application’s user interface (UI) and API.

This approach allows you to stream data and trigger actions instantly from both the front-end and back-end. Whether it's visualizing real-time data or triggering Spark computations via API calls, you can interact with your Spark environment with zero delay. This enhances the responsiveness of your applications and enables rapid decision-making with real-time insights.

Explore Spark Ecosystem
Article Banner

Managed Spark Cluster

Utilize a Managed Spark Cluster to simplify the deployment, management, and scaling of Apache Spark workloads. With a managed solution, you can focus on data processing and analytics while the underlying infrastructure is handled automatically.

A Managed Spark Cluster provides auto-scaling, monitoring, and seamless integration with storage and compute resources, ensuring your Spark jobs run efficiently. This eliminates the need for manual configuration, making it easier to optimize performance and reduce operational overhead. The managed environment offers a reliable and scalable platform for running big data workloads without the complexity of maintaining a cluster yourself.

Article Banner

Flexible Deployment, Your Choice

Cloud, On-Premises, or Hybrid – Ilum adapts to your setup

Run and manage your data solutions across any environment, giving you the freedom to choose what works best for your infrastructure.

Cloud, On-Premises, or Hybrid – Ilum adapts to your setup

Debug Seamlessly All in One Space

Streamline your development process by using an integrated environment that allows you to debug seamlessly across all components of your application. With everything in one space, you can monitor, troubleshoot, and fix issues in real-time without the need to switch between different tools or platforms.

This approach offers comprehensive debugging tools, allowing you to track logs, monitor performance, and inspect errors across the full stack—whether it's backend services, APIs, or the user interface. By having a centralized debugging workspace, you improve efficiency and reduce the time it takes to identify and resolve issues, ensuring a smoother development and deployment cycle.

Article Banner

Check how it works

Our Plans Scale with Your Needs. From Free to Enterprise Solutions

Flexible Plans for Every Need: Start Free, Scale as You Grow

Basic

Community

Your own Managed Data Lakehouse

Free Forever

Get Started!
Feature is Present

Cloud / Onprem / Hybrid

Feature is Present

Multi cluster support

Feature is Present

Interactive Sessions

Feature is Present

Free - your forever-free tier license

Read More
Advanced

Enterprise

Dedicated support, and custom configurations

Feature is Present

Priority Enterprise Support

Feature is Present

Custom modules/integrations

Feature is Present

Dedicated Engineer

Feature is Present

Custom SLA

Feature is Present

Onboarding, Training, and Migration Support

Read More
Coming soon!

Managed Cloud

Automation plus enterprise-grade features

vCPU based

Contact Sales
Feature is Present

Choose your zone

Feature is Present

AWS / GCP / Azure

Feature is Present

Free help with Migration

Feature is Present

Auto Scaling

Feature is Present

Custom Data Retention

Read More

Have some ideas how to improve Ilum?

We value your feedback and are always eager to improve. If you have suggestions that could enhance your experience or make navigating the product easier, please let us know. Join us in shaping the future of our platform! Your input matters.

Add feature request